 Nic Dunn, CEO, Charle Agency
What Is A/B Split Testing?
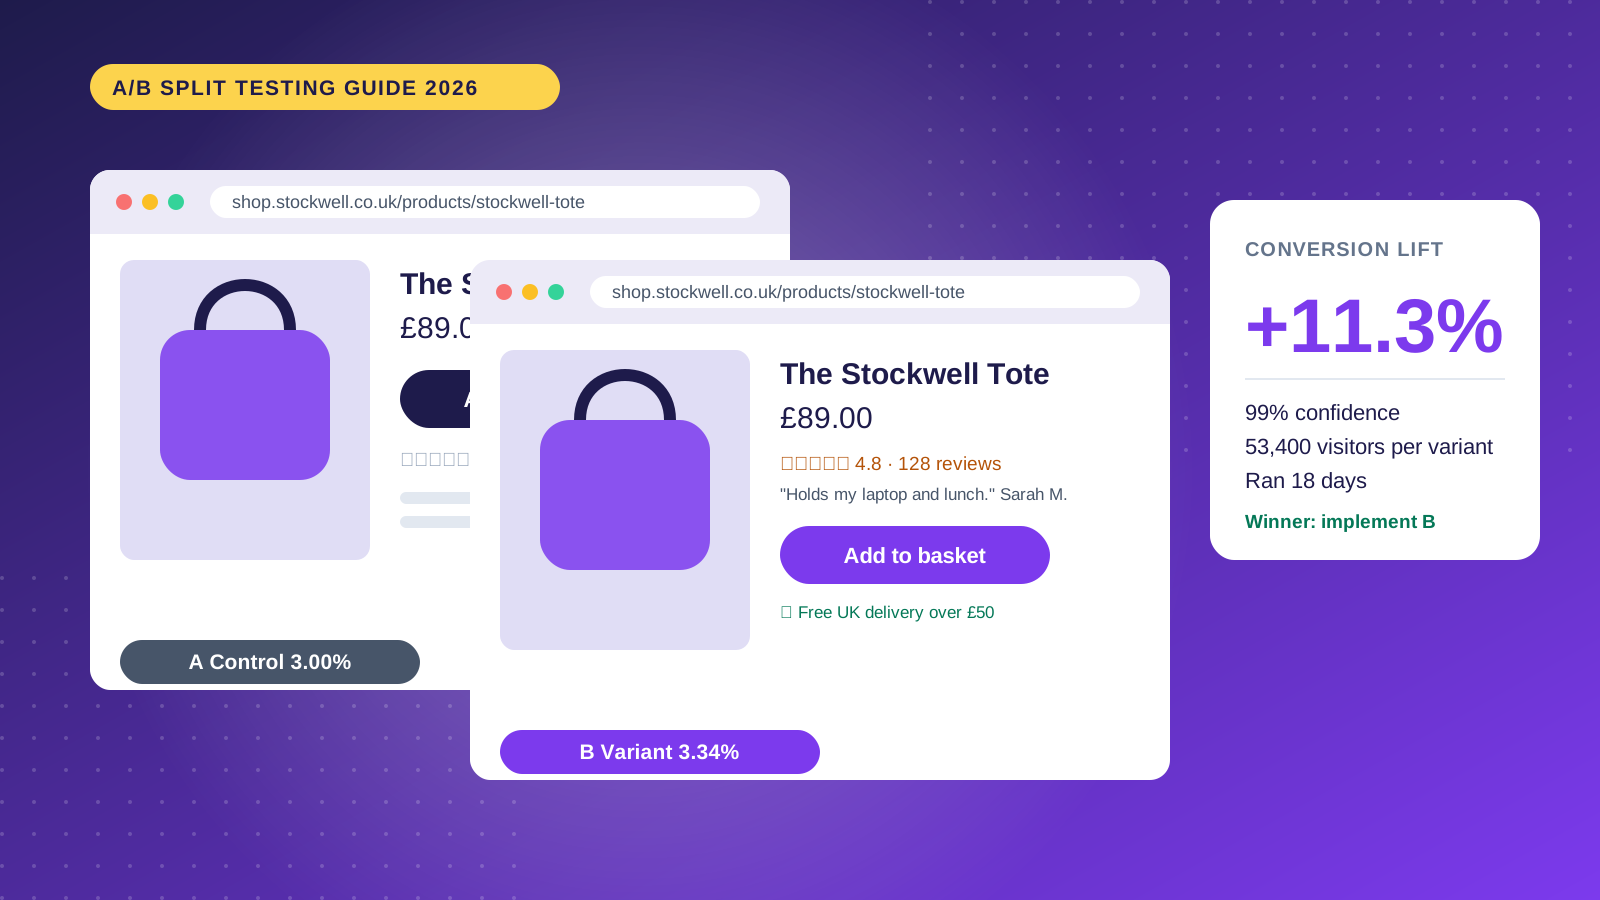
A/B split testing, also called A/B testing or split testing, compares two versions of a web page, email or app feature by showing version A (the control) to one group of visitors and version B (the variant) to another, then measuring which version produces more of a chosen outcome, such as purchases, clicks or sign-ups. A winner is only declared once the result is statistically significant, so chance does not make the decision for you. Marketers and product teams use it to evaluate headlines, layouts, button color, call to action wording, personalization and emails, and the outcomes feed directly into conversion rate optimization (CRO).
A basic test works like this:
- You identify something you want to improve, such as a button, a headline or a form field.
- You create variations of it, changing only that one element, so the audience sees two clear versions.
- Your testing tool randomly splits incoming traffic between the control and the variant.
- You collect data on how users behave with each version.
- Once the result reaches statistical significance, you analyze it and implement the winner.
The split is usually 50/50. The key principle is isolation: you change one thing at a time so you know exactly what caused any difference in performance and which way the result points. This guide covers the method, the statistics, the SEO rules, the tools and how to apply split testing on Shopify.
Why A/B Testing Matters
Without testing, decisions come from opinion and guesswork: the loudest voice in the meeting, the CEO's hunch, the designer's preference. Testing replaces that with evidence, so decisions rest on data rather than gut feel.
Intuition is less reliable than most teams assume. Ronny Kohavi, who led experimentation at Microsoft, reports in Trustworthy Online Controlled Experiments (2020) that roughly a third of ideas improve the metric they target, a third have no effect and a third make it worse. Google reported running 17,523 live traffic experiments in 2019, which led to 3,620 launches. Roughly four in five ideas never shipped.
Measurement also gives businesses information that opinion cannot: how customers behave, which things drive clicks and engagement, and how the effectiveness of each variation compares with the control. A steady program builds a library of answers about your audience, and that evaluation shapes your marketing strategy and every campaign you run.
Small wins compound, and measuring the effectiveness of each change keeps the program honest. A 2% improvement repeated 50 times produces a 169% overall gain, because each win builds on the last. No single test delivers that, but a steady program of experiments does.
There is a defensive benefit too. A new checkout flow that looks better in a meeting may damage user experience and increase cart abandonment, and a test catches that before the change reaches 100% of visitors.
Revenue impact is tangible. For ecommerce, a 10% conversion rate lift on $100,000 of monthly revenue is an extra $10,000, and conversion rate optimization of this kind is one of the cheapest ways to grow without buying more traffic.
A/B Testing vs Split URL Testing vs Multivariate Testing
These terms are often used interchangeably, but they are different types of test with different use cases. Choosing the right one early saves wasted effort.
A/B Testing
A/B testing runs both versions on the same URL. Your testing tool loads the control by default, then uses JavaScript to swap in the variations for the test group. You might change a button color, a headline or a form field. It is fast to set up and suits most pages.
Split URL Testing
Split URL testing, sometimes called redirect testing, serves the control on one URL and the variant on another. It suits radical redesigns or a different page structure that JavaScript cannot swap in cleanly. The cost is more development work and some SEO care, covered below.
Multivariate Testing (MVT)
Multivariate testing changes several variables at once, for example button color, button text and button size in one experiment. Three variables with two options each create eight combinations, and every combination needs its own sample. MVT only works on pages with very high traffic. Start with A/B testing and move to MVT when you have thousands of monthly conversions.
How to Run an A/B Test: Step by Step
A well-run test follows a structured process and the best practices below. Skip steps and you will generate misleading results.
1. Research and Define Your Goal
Split testing is for validating ideas, not finding them. Start with analytics, heatmaps, session recordings and customer reviews to see where users drop off and how they behave, then set a specific goal. "Improve performance" is not a goal. "Increase product page add-to-cart rate by 5% without lowering average order value" is.
2. Form a Hypothesis with a Because Clause
Say why you think the variant will win: "We will move reviews above the add-to-cart button because shoppers drop off before seeing proof, and our heatmaps show most visitors never scroll to the reviews." Writing hypotheses down forces clear reasoning and means you learn something even when the variation loses.
3. Choose Your Metrics
Pick one primary KPI that proves or disproves the hypothesis, such as conversion rate or revenue per visitor, and define success as a specific percentage before you launch. Add secondary metrics for context, such as click-through rate and engagement, and guardrail metrics that must not get worse, such as average order value, refund rate, bounce rates or page performance. Avoid proxy metrics like pageviews when you care about revenue.
4. Select Your Testing Tool
Choose based on your platform, technical ability and traffic volume. The main options are covered later.
5. Build Your Variant
Change exactly one thing per variation, or one clearly defined concept. If you change the button text, the color and the content above it, you will not know what drove the result. Make the difference visible enough for each audience group to notice, and keep everything else identical. Two or three variations are enough for most business goals, because every extra variation needs its own share of traffic.
6. Calculate Sample Size and Duration
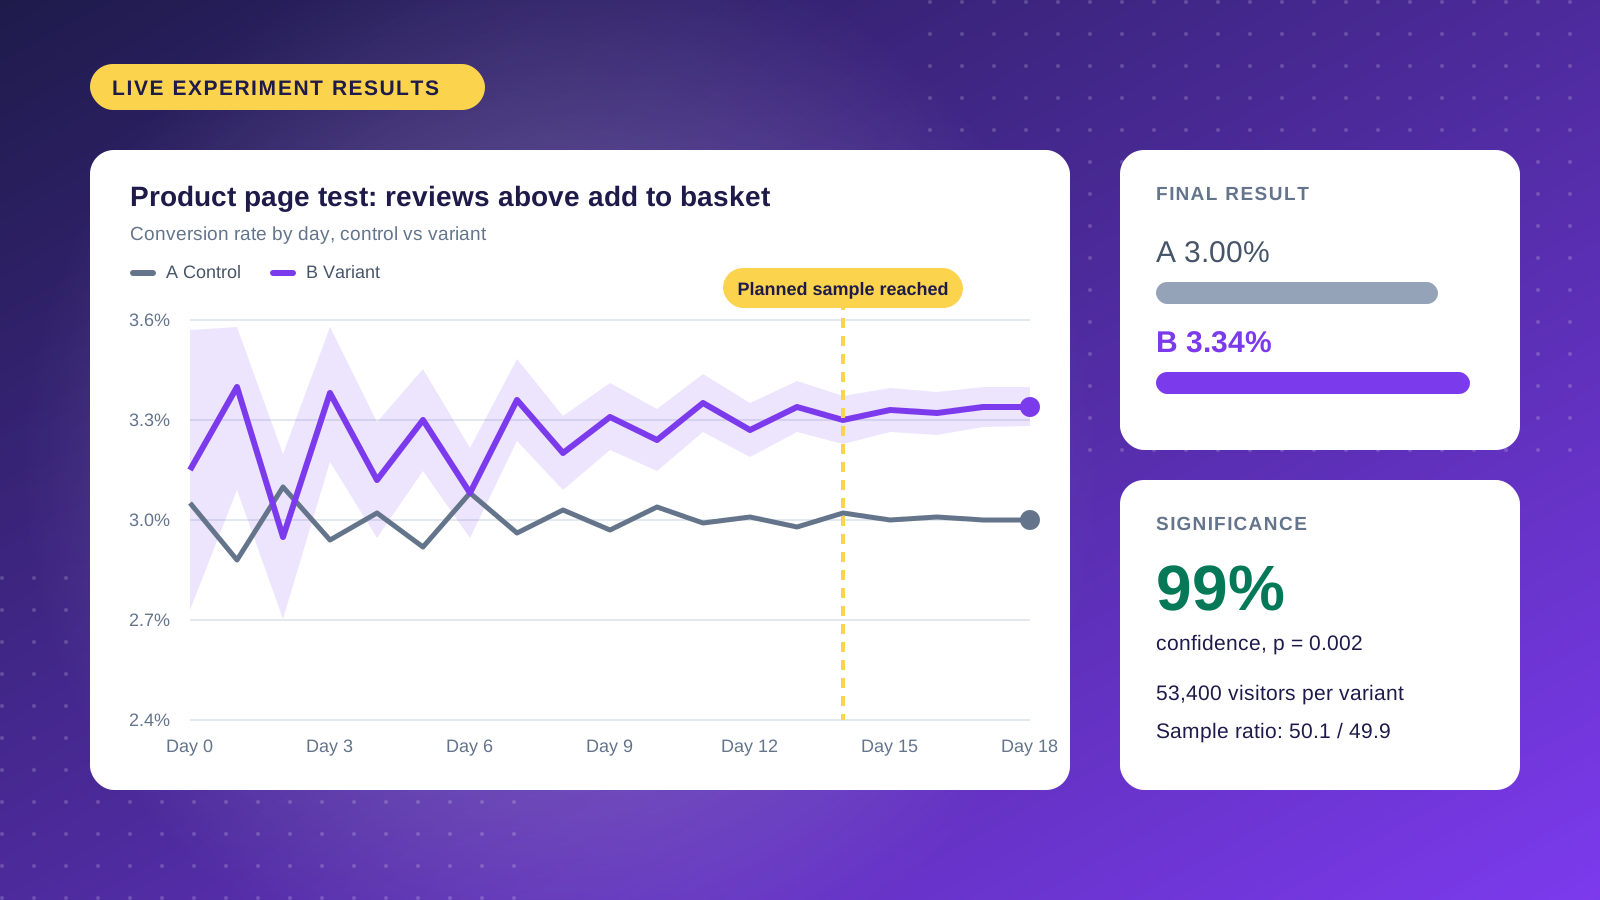
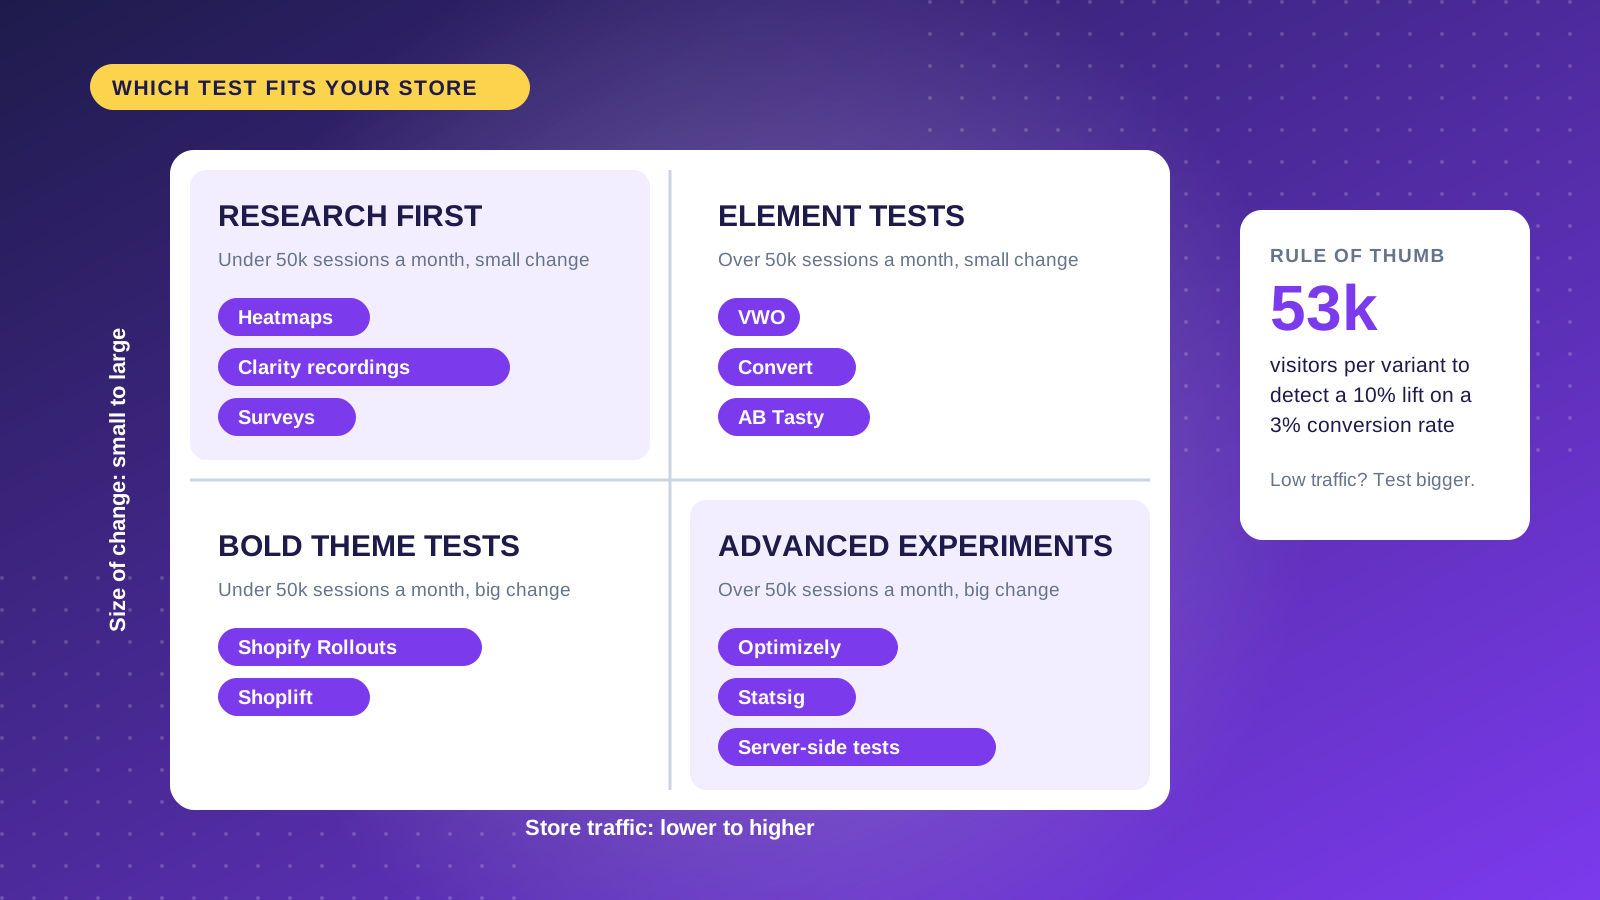
Use a sample size calculator before launch. The inputs are your baseline conversion rate, the minimum detectable effect (the smallest lift worth finding) and your confidence level, usually 95%. As a worked example, a store converting at 3% that wants to detect a 10% relative lift (3.0% to 3.3%) at 95% confidence and 80% power needs around 53,000 visitors per variant. A store with 40,000 monthly sessions would need almost three months, which is why low-traffic stores should test bigger changes. Run all tests for at least two full weeks to cover day-of-week effects.
7. Analyze Results and Act
Once you reach your planned sample size, check the results for statistical significance, implement the winning version and document the learning. If neither version won, record that and move on. If the outcome surprised you, segment the data by device and new versus returning visitors.
What Should You A/B Test?
Almost anything on your web pages can be tested. The question is what is worth testing given your traffic and business impact. These features and elements consistently produce insights:
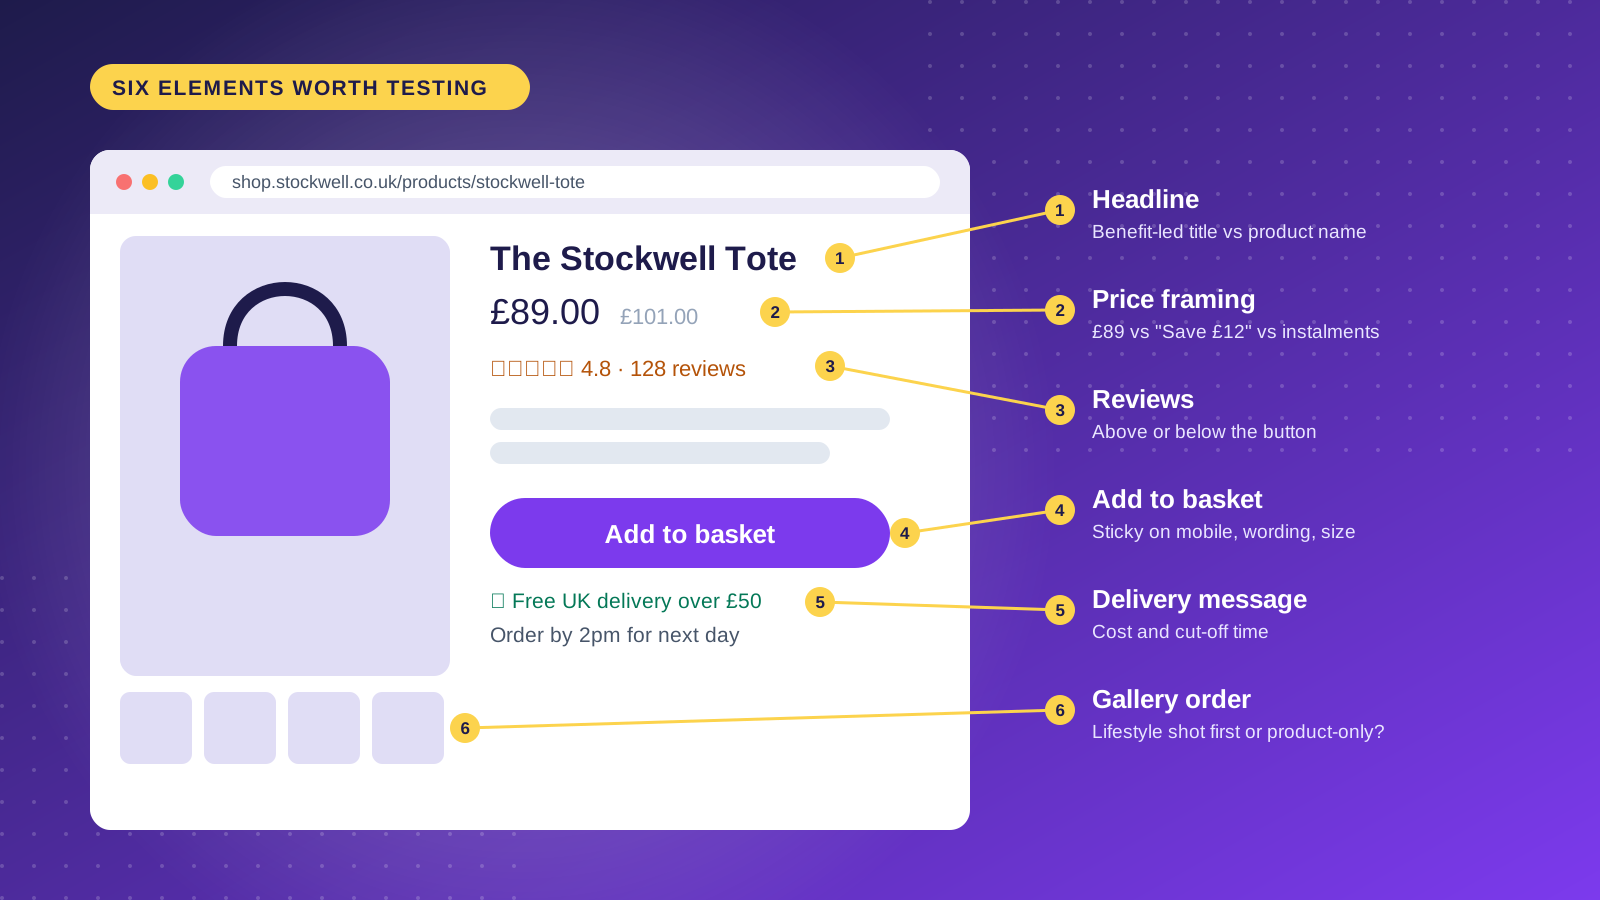
Headlines and Copy: The headline is the first thing people read, so it often moves clicks and engagement most. Benefit-led versus curiosity-led language, short versus long copy, and the way each speaks to your marketing audience.
Calls to Action (CTAs): Test button color, size and placement as well as action-oriented wording ("Get Started Now") against softer wording ("Learn More"), since the CTA is the point where users commit.
Landing Pages: Hero images, page design, headline copy, form length and trust signals. If you run paid campaigns, the landing page is where conversions happen.
Forms: Field count, field order and required versus optional fields. Shorter forms usually raise submissions but can reduce lead quality.
Images and Video: Product photography style, lifestyle versus product-only imagery, and the presence of video on pages for your products.
Pricing and Offers: Price points, discount framing ("30% off" versus "Save $12") and subscription versus one-time messaging. Urgency elements such as countdown timers can lift conversions but may erode margin.
Navigation and Layout: Funnels leak where navigation confuses people. Menu structure and search prominence affect user experience and how easily people find what they need.
Social Proof: Testimonials, review counts and trust badges generally help, but test whether your version moves your metric.
Understanding Statistical Significance
Say the variant shows a 12% higher conversion rate than the control. Should you implement it? Not necessarily, because variation happens by chance. Statistical significance tells you whether the difference in performance is real or random error, so evaluation of results should start with the significance threshold, not the percentage lift alone.
The standard in digital testing is 95% confidence: if there were truly no difference, you would see a result this extreme less than 5% of the time. Three factors determine whether you reach it:
Sample Size: More visitors let you detect smaller differences. With 10,000 users per variant you might detect a 1% difference, while with 100 users you need a 15% difference.
Effect Size: A 2% difference needs a far larger sample than a 20% difference.
Baseline Conversion Rate: A 10% improvement on a 50% baseline is easier to detect than a 10% improvement on a 1% baseline.
Frequentist vs Bayesian Testing
Most testing tools use one of two statistical methods. The frequentist method fixes the sample size in advance, then reports a p-value once the test ends. The Bayesian method reports the probability that B beats A and updates as data arrives, which many teams find easier to read. Whichever you use, agree your stopping rule before launch.
Peeking and Sample Ratio Mismatch
The most common analysis error is peeking: checking results mid-test and stopping the moment they look significant. Classic research on repeated significance tests shows that ten looks can lift a nominal 5% false-positive rate to roughly 19%. Decide the sample size in advance, then wait.
A second check is sample ratio mismatch. If you configured a 50/50 split and a large test comes back 53/47, something is broken, often a redirect, caching or bot-filtering problem. Treat the results as unreliable until you find the cause.
Does A/B Testing Hurt SEO?
Not when it is done properly. Google's own website testing guidance says testing will not harm your rankings if you follow four rules:
- No cloaking. Show Googlebot the same content a typical visitor would see. Do not use visitor segmentation to serve crawlers a different page.
- Use rel="canonical" on split URL tests. Point every variant URL at the original so the variants are not indexed as duplicates.
- Use 302 redirects, not 301s. A 302 signals that the redirect is temporary and the original URL remains the one to index.
- Run tests only as long as necessary. Once you have a winner, implement it, remove the test setup and delete any variant URLs.
Page performance is the other SEO risk. Client-side tools load extra JavaScript, and anti-flicker snippets can delay rendering and hurt Largest Contentful Paint. Server-side tests avoid both problems because the variant is chosen before the page is sent.
The Best A/B Testing Tools in 2026
Google Optimize, the free tool many companies relied on, shut down in September 2023, which reshaped the market. These are the software platforms worth considering. Most offer a free trial or a demo, so try one on a low-risk page before you commit:
Optimizely: The enterprise standard. Feature-rich, with strong audience segmentation and pricing on request. Best for teams running dozens of tests a month.
VWO (Visual Website Optimizer): A mid-market choice that combines A/B testing, heatmaps, session recordings and form analytics in one platform.
AB Tasty: A European alternative with a GDPR-friendly approach and strong personalization features.
Convert: Privacy-focused, with data ownership and no reliance on third-party cookies.
LaunchDarkly and Statsig: Server-side feature flags and experimentation for engineering teams that want testing built into their release process.
For Shopify stores, dedicated apps integrate more smoothly with your theme and admin.
A/B Split Testing for Ecommerce and Shopify
Ecommerce suits A/B testing well, and brands that treat UX as a measurable discipline tend to pull ahead. You have clear conversion events, steady traffic and direct revenue impact. A 5% conversion lift on a store doing $50,000 a month is $2,500 in new sales, and every optimization compounds.
Product Pages
Product pages are the most-tested page type in ecommerce. Test image prominence, the order of description and reviews for your products, social proof near the price, and a simpler add-to-cart flow. Change the layout and design, not just the text, because layout changes produce bigger effects that small stores can actually detect.
Collection Pages
Test grid versus list layouts, the number of products per page, filter prominence and default sort order. These decisions shape how quickly users find what they want.
Checkout Flow
Cart abandonment sits at roughly 70% across ecommerce, so checkout tests are high-value. Test guest checkout versus account creation, form field reduction, trust signals at each step and progress indicators. Shopify limits how far you can change checkout outside Plus, so check what your plan allows before planning a test.
Native Testing with Shopify Rollouts
As of March 2026, Shopify offers native A/B testing through Rollouts, available to merchants on Basic plans and above. Rollouts lets you schedule theme changes, set an end date so your store reverts automatically after a promotion, and run A/B tests that compare a changed theme against your current one with real traffic. You review conversion impact and choose the winner in the Shopify admin under Markets > Rollouts. Merchants on Advanced and Plus plans also get market-specific targeting for regional promotions or localized homepages.
Rollouts is a solid start for stores new to experimentation, but it focuses on theme-level changes. For multivariate tests, deeper segmentation, server-side experiments or tests beyond the theme, third-party apps still offer more.
Third-Party Apps and Shoplift
Shoplift is our top app recommendation. It is Shopify Plus Certified, works through the theme customizer with no code injection, and its Lift Assist feature surfaces statistical recommendations from your test data. For a full comparison of tools built for Shopify, see our guide to the best A/B testing tools for Shopify.
A/B testing is one part of a wider conversion strategy, and measurement of outcomes should feed every campaign. For a more structured approach to growing store performance, see our Shopify CRO services, or read our guide to improving your ecommerce conversion rate.
Common A/B Testing Mistakes
Most teams make the same avoidable errors. Knowing them before you start protects your results.
Stopping Early: Promising results after one week are often natural variation that reverses later. Run the test for the full duration you calculated.
Testing Too Many Variables at Once: If you change the headline, button wording, form fields and layout together, you cannot tell which change worked. Isolate variables.
Ignoring Devices: Mobile and desktop visitors show different behavior. Changes that lift desktop conversion can hurt mobile, so segment by device or make sure each device has enough sample.
The HiPPO Problem: The Highest Paid Person's Opinion overrides the test result. Agree before launch that the data decides.
Not Segmenting Results: A variant can win overall while new customers prefer it and returning customers prefer the control. Look beyond top-line numbers before you roll out.
Novelty Effect: People interact with something simply because it is new. The effect fades within days, so run tests long enough to move past it.
Ignoring Privacy Rules: Testing tools often set cookies. Check your consent set-up against GDPR, the ePrivacy rules and US state privacy laws such as the CCPA before you launch.
Failing to Document Learnings: A test ends, the winner ships and the reasoning disappears. Record every hypothesis and result, win or lose.
Building a Testing Culture
One test proves a point. A program of iteration compounds into competitive advantage.
Create a Testing Roadmap: Do not run experiments randomly. Pick your business priorities, such as checkout abandonment or average order value, then list the experiments most likely to move them.
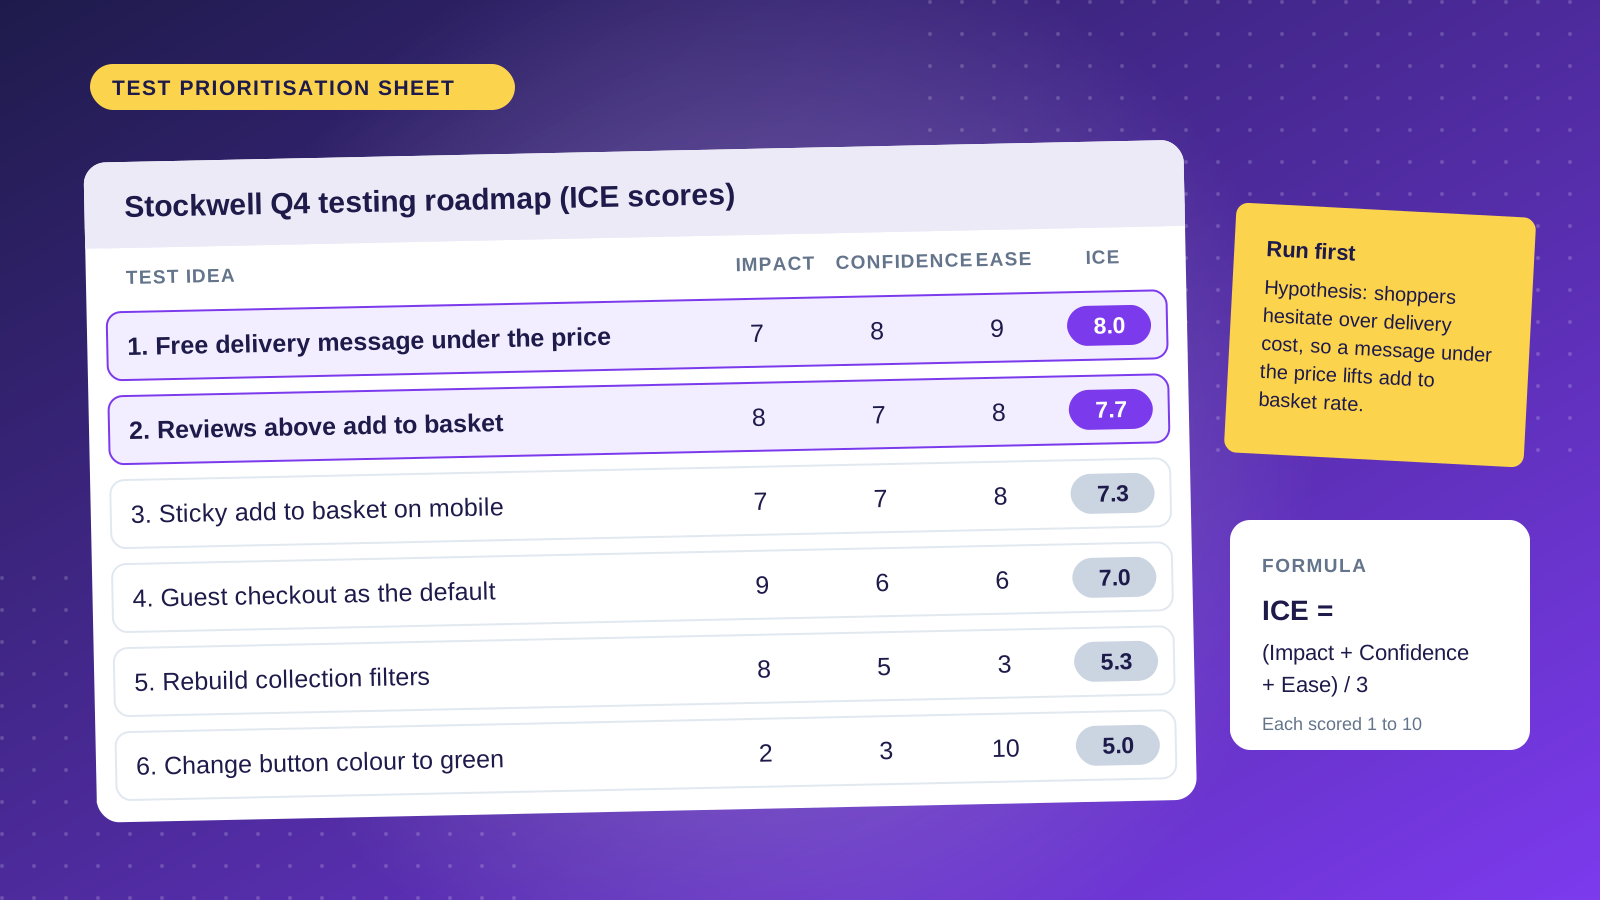
Prioritize with the ICE Framework: Score each idea on Impact (how much revenue if it works), Confidence (how likely you think it is to work) and Ease (how quickly you can build and run it). Run high-scoring tests first.
Document Everything: Keep hypotheses, results, learnings and decisions in a shared spreadsheet or wiki. New team members should be able to see what you have tested and why.
Expect Modest Wins: Most tests will not produce dramatic uplifts. A program of 20 tests a year in which half deliver a 5% to 15% lift still compounds into a large annual gain. Judge the program on cumulative impact.
Why We Split Test on the Server, and Why Most Stores Should Test Bigger Changes
On our own site we run our own split tests with a PHP cookie that assigns each visitor to a variant before the page renders. We tag those sessions in Microsoft Clarity and read the results in PostHog. Because the variant is chosen on the server, there is no flicker, no JavaScript swap and no extra script slowing the page. That set-up suits a custom-built site such as ours, and our team chose it because our company strategy depends on fast pages.
Our view is that most Shopify stores run the wrong kind of test. They have 20,000 to 50,000 monthly sessions, a conversion rate near 2% and a testing roadmap full of button colors. At that traffic a 3% relative lift takes months to detect, so the test either never finishes or gets called early on noise. We would rather see a store of that size test one bold change per quarter, such as a rebuilt product page layout or a new delivery message, and run it long enough to trust. Small stores should also spend their first months on research, because a good hypothesis is worth more than a faster tool.